
Can the studio train on CUDA 13.4?
The question
Section titled “The question”The Director’s rule is to train on the newest stack the rig can handle. CUDA 13.4 shipped in October 2026. Could we use it on the RTX 5090, and on rented RunPod GPUs whose hosts run the older CUDA 13.0 driver?
What we found
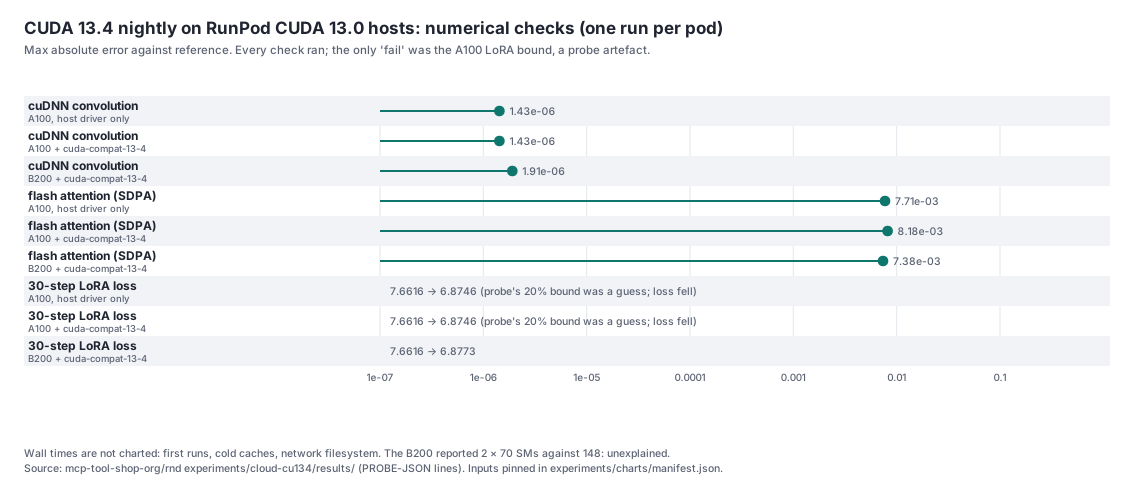
Section titled “What we found”- On RunPod’s CUDA 13.0 hosts, a CUDA 13.4 PyTorch nightly runs. It passed on an A100 and a B200: Triton,
torch.compile, CUDA graphs, cuDNN and flash attention all worked. - NVIDIA’s forward-compatibility package (
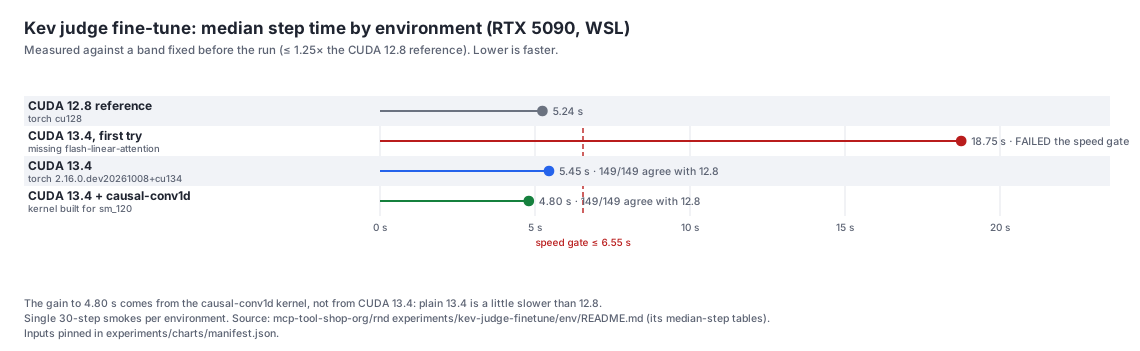
cuda-compat-13-4) gives a real 13.4 driver API on those hosts. The driver version the probe reads goes from 13000 to 13040. - The judge fine-tune (Kev) passes its pre-set band on CUDA 13.4. Its verdicts agree with the CUDA 12.8 reference on 149 of 149 pairs, and its confirm score is identical (0.9799).
- The speed-up is from a kernel, not from CUDA. Plain CUDA 13.4 ran a little slower than 12.8 (5.45 s vs
5.24 s per step). Adding the
causal-conv1dkernel, built for the 5090, brought it to 4.80 s. - The first CUDA 13.4 try was 3.6× slower (18.75 s per step) because the environment was missing flash-linear-attention. A speed gate now catches that.
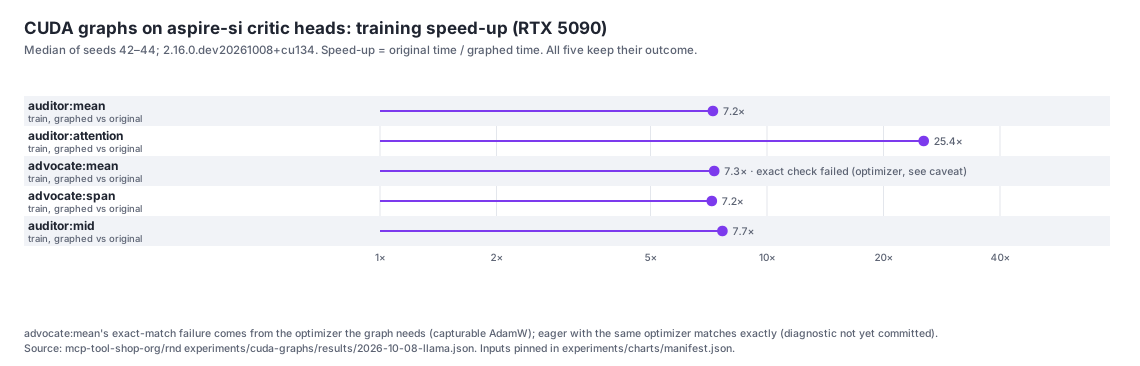
- CUDA graphs speed up aspire-si’s small critic heads 7.2–25× in training, on the 5090.
torch.compileworks on Windows with the CUDA 13.4 nightly and triton-windows.- An install trap: with
uv,--extra-index-urloutranks--index-url, so a CUDA install silently gave a CPU-only torch. It happened twice.
| Kev environment | median step | agreement with CUDA 12.8 |
|---|---|---|
| CUDA 12.8 reference | 5.24 s | (reference) |
| CUDA 13.4, missing flash-linear-attention | 18.75 s (failed the speed gate) | not run |
| CUDA 13.4 | 5.45 s | 149/149 |
| CUDA 13.4 + causal-conv1d | 4.80 s | 149/149 |
Caveats
Section titled “Caveats”- Rented-GPU wall times are not speeds. The B200’s compile and fine-tune times were a first run on a cold cache over a network filesystem.
- The B200 reported 2 × 70 = 140 processor units against the 148 it has. That’s unexplained, so it’s an open question, not a fact.
- One of the five graphed heads failed the exact-match check. The cause was the optimizer setting the graph needs (capturable AdamW), not the graph: the eager run with the same optimizer matched exactly. That diagnostic isn’t committed as a receipt yet.
- The causal-conv1d bf16 check was changed after its first run failed. This is disclosed, and the Publisher reviewed and agreed.
- A 2026-10-07 entry said no CUDA 13.2 or 13.4 PyTorch wheels existed. A day later they did; the entry is superseded.
Receipts
Section titled “Receipts”mcp-tool-shop-org/rnd:
experiments/cloud-cu134/(A100 and B200 probes, compatibility runs, costs; commits 8d51217, 5850199, 89059db);experiments/kev-judge-finetune/env/README.mdand its results;experiments/cuda-graphs/(results/2026-10-08-llama.json, the bench log and the Triton probe; 00f57b4, 3245230);- the 2026-10-07 entries on the rig’s CUDA stack and the
uvindex trap.